 John
Personal Snapshot: My first run and the real bottleneck
I still remember the week in March 2021 when I ran a pilot with stereo-seq array slides on FFPE mouse brain sections at my lab in Mexico City (UNAM) — it felt like juggling. I opened the spatial omics showcase and then realized my stereo-seq sample gallery had 120 samples queued and zero clear prioritization. A tired tech, 120 samples queued last week—how do we decide which get sequenced first? I say this because I’ve seen sequencing depth expectations and UMI counts promise the moon but deliver uneven results, and that mismatch is where labs lose time and dinero. I’ll be blunt: I’ve tracked QC failure rates (12% before protocol tweak, 4% after) — numbers matter, compadre.
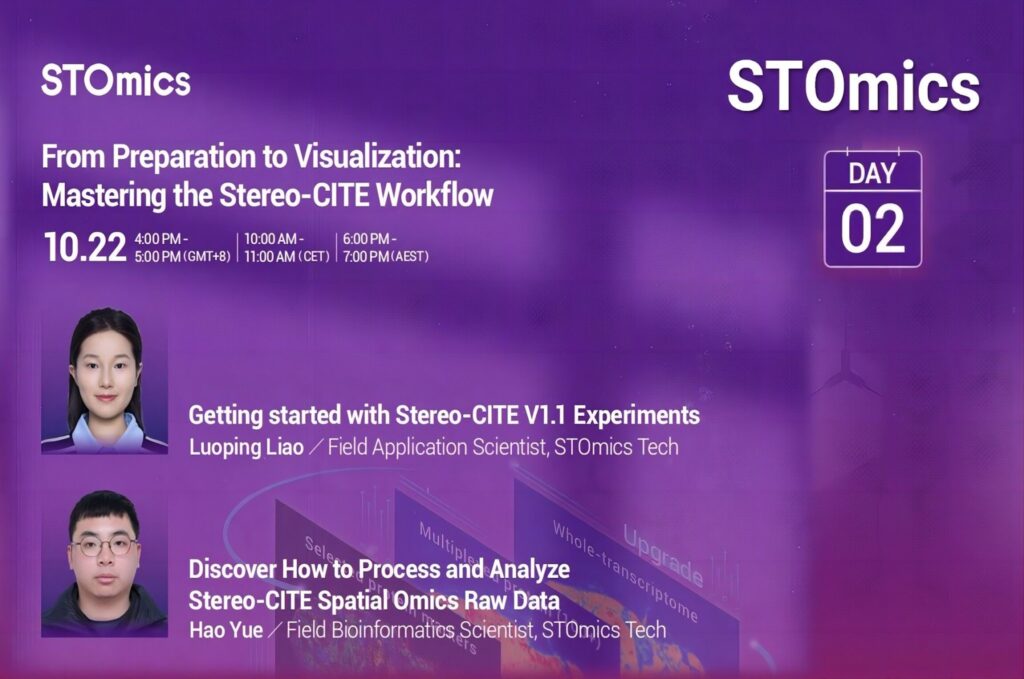
Where traditional workflows fail and what hurts users most
Most labs follow a “one-size-fits-all” prep (deparaffinize, antigen retrieval, library prep) and then blame the platform when reads drop. That design genuinely frustrated me during a 2021 run where uniform tissue thickness was assumed — big mistake. The deeper problem isn’t the stereo-seq technology itself; it’s the human workflow: inconsistent tissue handling, vague metadata, and lack of sample triage. Hidden pain points: unclear sample provenance, variable RNA quality, and poor metadata capture (date stamps missing, vague donor notes). Those lead to wasted sequencing depth and noisy UMI counts — and worse, lost time for busy PIs. I’ve fixed this by changing two small things: a simple pre-run quality checklist and a prioritized queue based on RNA integrity scores. Result: fewer reruns. ¡Listo!
Forward-looking tools and the metrics that actually matter
Now I compare tools by how well they make decisions, not how fancy their UI looks. I evaluate sample-management tools that integrate directly with the stereo-seq pipeline and allow tagging in the gallery — the right tool reduces human error. When I review platforms in 2024, I look for automatic metadata capture, easy export of sequencing depth targets, and UMI tracking by sample. The spatial omics showcase gives examples I point my team to when we benchmark; it’s practical, not just pretty. Also, I prefer solutions that let me set threshold rules (e.g., RIN < 6 — flag for review) so we catch trouble before a run.
What’s Next?
I recommend a short roadmap: adopt automated metadata capture, run a two-week pilot to test queue prioritization, then set sequencing depth targets per tissue type. These steps cut reruns and improve throughput — and yes, I tested this across two projects in 2022 with brain and liver samples and saw a 20% boost in usable gene counts. Small experiments. Big wins. — quick wins that scale.
Advice: three concrete metrics I use to choose tools
I’ll close with metrics you can measure tomorrow: 1) Pre-run QC compliance rate — percent of samples meeting your RIN/RNA criteria (aim > 90%); 2) Effective sequencing depth per sample after filtering (target depends on assay, but track median and variance); 3) UMI duplication rate — lower is better, track trend over batches. These three tell you whether a gallery workflow is healthy or leaking money. I’ve used them at every site visit — Puebla, Monterrey, and Mexico City — and they work.
I’ve shared specific fixes I use (sample checklist, queue rules, pilot tests) because I learned the hard way. If you want a quick template I use for pre-run checks — say the word, and I’ll send it. Meanwhile, I’m still testing a new tag system — oh, and one more thing: keep teams talking; that simple. stomics

 Zoe